Which image embedding to use for the UMAP of evolved robots. Part of E02 Persona evolution runs. Created 2026-11-17.
Miyazaki embedded each robot’s four-frame strip with CLIP and ran UMAP on the vectors. Reiji asked for newer methods.
The candidate is EmbeddingGemma 2 (2026-10, Apache 2.0), which takes the four frames as four images of one input.
Status: all four embeddings run on kodama (2026-11-18). None beats raw silhouettes on lineage; DINOv3 and CLIP per frame are the best models.
Candidates
| Embedding | What it captures | Role |
|---|---|---|
clip-strip | Caption-level semantics | Closest to Miyazaki (strip letterboxed to a square, nothing cropped) |
clip-frames | Same, per frame | CLIP without the squashed strip |
egemma2 | Semantics, shared space with text | Main “newer” candidate |
dinov3 | Shape and geometry, no text | Self-supervised contrast |
genotype, pixels | Voxel-type Hamming; 32×32 silhouettes | References, no model |
Expectation: our images are flat red silhouettes, so language-aligned models (CLIP, EmbeddingGemma 2) may see them all as “a red blob”, while DINOv3 tracks shape.
Script
work/scripts/embed_compare.py, dependencies in the uv group embed (torch, torchvision, transformers, sentence-transformers, umap-learn, scikit-learn):
cd work && mise exec -- uv run --group embed python scripts/embed_compare.py --prefix E02.1_beautifully- Input: the strips
robots/gen_XXX/idNN.pngof each run’s last generation (render_generation.pyon a Linux host).--generation Npicks another. - Robots with the same body in the same run count once (479 of 600 for E02.1 beautifully).
- Measures, from each robot’s 10 nearest neighbours (cosine):
- Lineage: share of neighbours with the same generation-0 founder and seed
- Condition: share of neighbours from other runs with the same persona
- Body R2 / Motion R2: neighbours’ mean predicts voxel counts / displacement and path length
- Hamming rho: Spearman between embedding distance and voxel Hamming
- Trust: trustworthiness of the 2D UMAP
- Output in
out/analysis/embed/<prefix>/: cached vectorsemb_*.npz,metrics.csv,coords_*.csv,maps.png.
Results
E02.1 beautifully, last generation (gen 19), 20 runs. Chance: lineage 0.06, condition 0.21.
| Embedding | Lineage | Condition | Body R2 | Motion R2 | Hamming rho | Trust |
|---|---|---|---|---|---|---|
| genotype | 0.94 | 0.15 | 0.78 | 0.39 | 1.00 | 0.99 |
| pixels | 0.85 | 0.16 | 0.61 | 0.38 | 0.36 | 0.95 |
| clip-strip | 0.66 | 0.29 | 0.62 | 0.30 | 0.13 | 0.98 |
| clip-frames | 0.73 | 0.26 | 0.69 | 0.34 | 0.12 | 0.97 |
| dinov3 | 0.74 | 0.27 | 0.70 | 0.38 | 0.11 | 0.97 |
| egemma2 | 0.66 | 0.27 | 0.65 | 0.32 | 0.16 | 0.97 |
- Raw silhouettes keep lineage better than CLIP. CLIP per frame beats the strip.
- CLIP groups robots by persona a bit above chance (0.26–0.29 vs 0.21), where genotype and pixels do not. Not yet clear whether that is a real phenotype signal.
- DINOv3 ≈ CLIP per frame, marginally best of the models (lineage 0.74, body 0.70, motion 0.38). The shape-vs-semantics difference expected under Candidates did not show.
- EmbeddingGemma 2 is no better than CLIP: about equal to
clip-stripon every measure, belowclip-frameson lineage and body.
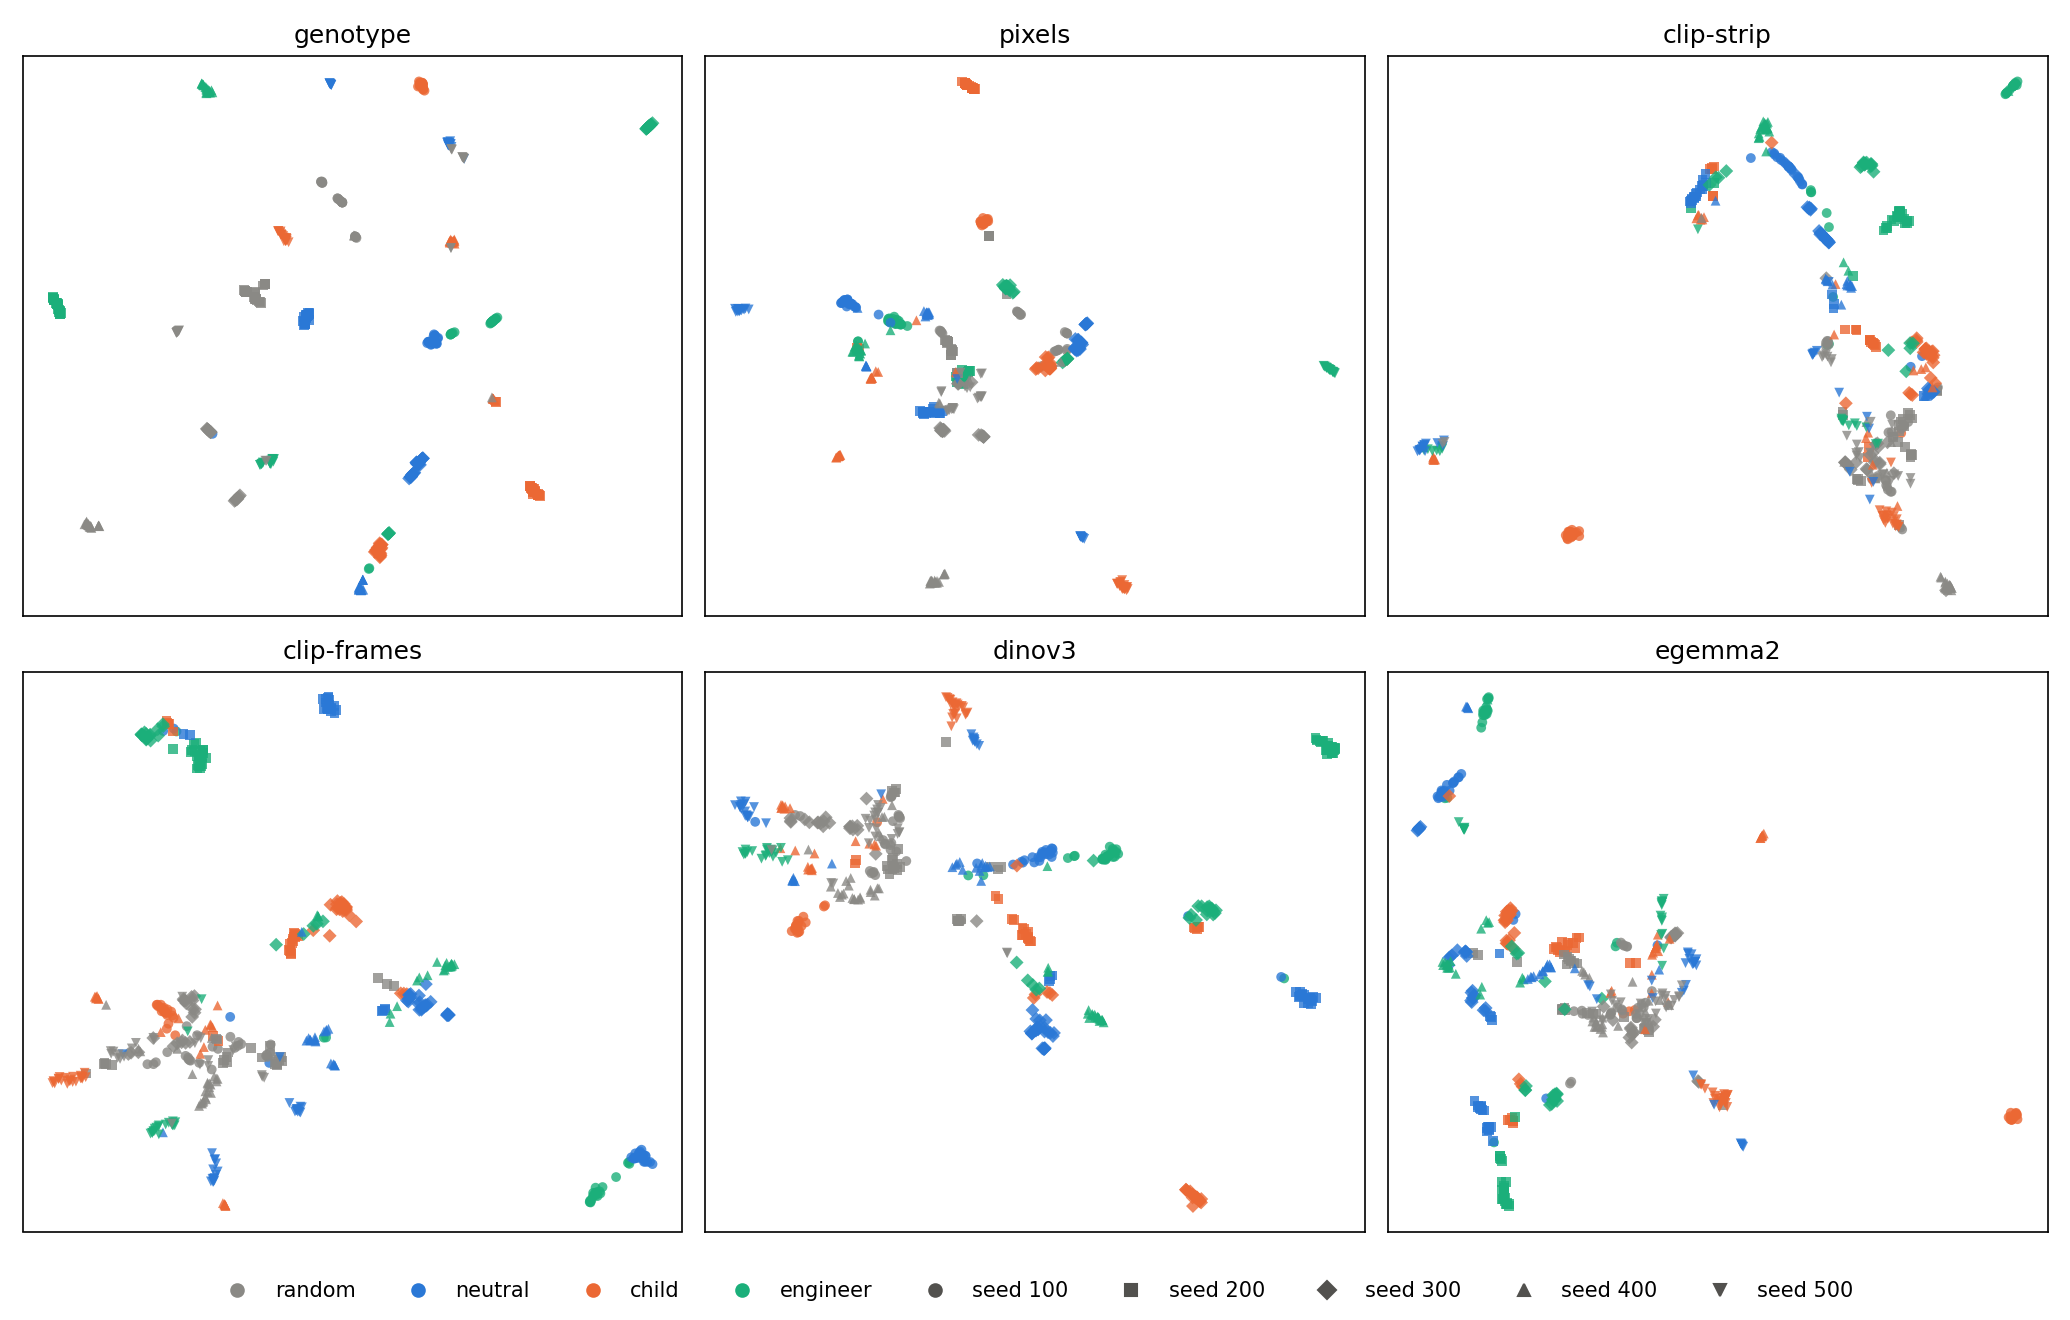
UMAP per embedding. Colour: persona (grey = random). Marker: seed.
- In every image embedding (
maps.png), the random runs form one mixed cloud in the middle, and the VLM runs form tight separate clusters, one per lineage. In genotype space random runs cluster by run like the rest. - CLIP results on kodama equal the Mac’s. Kodama: EmbeddingGemma 2 encoding ~1.5 min for 600 robots, whole script ~10 min including downloads; DINOv3 rerun ~1 min.
To do
-
git pull,uv sync --group embedon kodama; E02.1 beautifully settings, generations and gen-19 strips copied over with rsync (18 MB) - DINOv3 is gated: Ka accepts the licence on the Hugging Face page of
facebook/dinov3-vitb16-pretrain-lvd1689m, thenuv run --group embed hf auth loginon kodama (Ka’s token) - EmbeddingGemma 2 is not gated; ran on kodama 2026-11-18. On the Mac it failed first for missing torchvision (now in the group), then was killed (exit 137) while embedding, likely out of memory with the Mac’s 8 GB RAM. Its weights (1.5 GB) did download. Don’t run it on the Mac: the attempt on 2026-11-17 slowed the whole machine
- Rerun with DINOv3 (2026-11-18)
- Look at
maps.png; pick the embedding; then compare PCA or PaCMAP with UMAP on it
Open
- Embed the judge’s own vision tower (Gemma 4’s) to see what the judge sees?
- Video input to EmbeddingGemma 2 instead of four frames, once frames show motion over time (E02 Motion input).
- Diversity in the full embedding space, not on the 2D map.